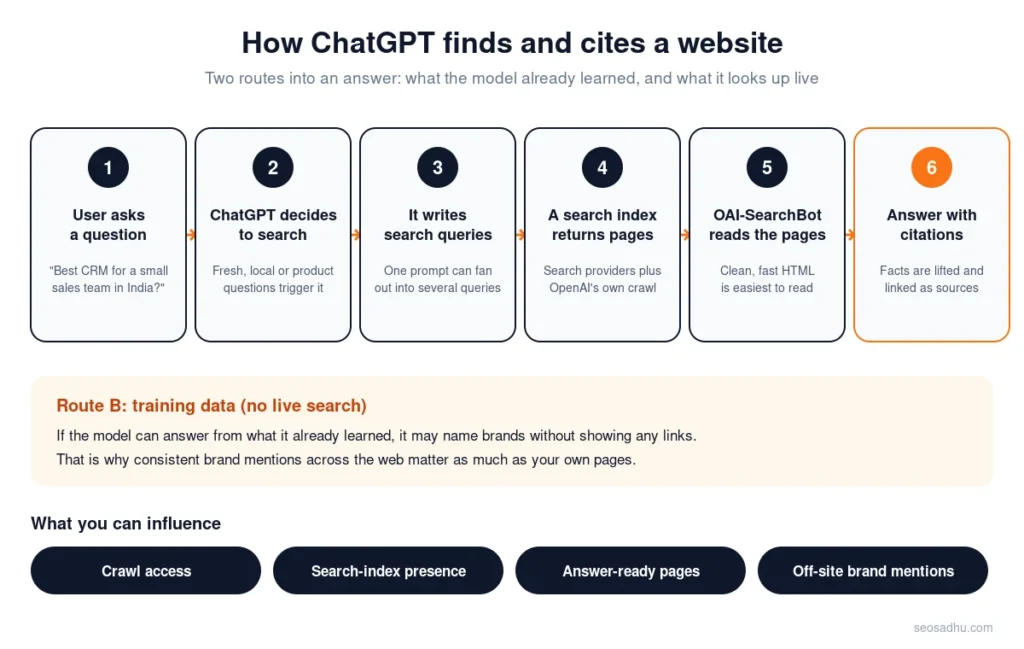
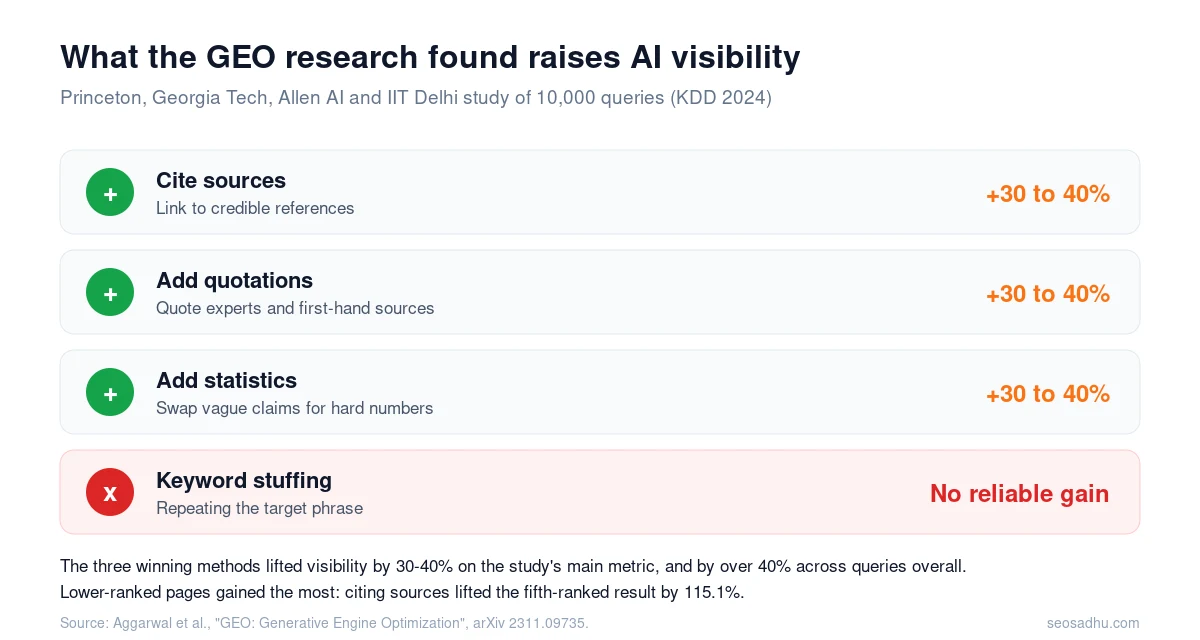
When a prospective customer asks ChatGPT, Google Gemini, or Claude to recommend the “best enterprise software for supply chain tracking,” how does the language model decide which brands to endorse and which to completely ignore? The answer lies in algorithmic brand authority—the mathematical vector weighting that AI systems assign to entities based on web-wide semantic consensus, entity disambiguation, and knowledge graph verification.
- The Vector Salience Metric: Large Language Models (LLMs) do not count backlinks like Google’s original PageRank. They measure semantic co-occurrence—how frequently your brand name appears alongside industry terminology in authoritative, peer-reviewed, and editorial training datasets.
- The Entity Disambiguation Imperative: If your brand does not possess a verified Wikidata entry, a Google Knowledge Graph ID, or consistent
sameAsstructured schema, LLMs treat your company as an unverified string of text rather than a recognized corporate entity. - Preventing AI Hallucination & Omission: Proactive Generative Engine Optimization establishes an indisputable corporate record across independent authoritative registries, ensuring AI models cite your products accurately without hallucinations.
How Large Language Models Construct Brand Trust
Modern LLMs evaluate corporate authority through three interconnected computational layers:
| Authority Layer | How the Model Evaluates It | Corporate Requirement |
|---|---|---|
| 1. Knowledge Graph Verification | Maps the entity against structured knowledge bases (Wikidata, Google Knowledge Vault). | Explicit Wikidata entry, Google Knowledge Panel, and complete Schema.org Organization markup. |
| 2. Semantic Co-Occurrence | Calculates vector distance between your brand and high-trust industry topics in training data. | Sustained tier-one digital PR coverage, expert executive quotes, and industry whitepapers. |
| 3. Real-Time Web Consensus | Cross-references live search indices to verify customer sentiment and product availability. | Verified third-party review presence on G2, Trustpilot, Gartner Peer Insights, and Reddit. |
The 4-Step Framework to Build Institutional AI Authority
1. Uncontested Entity Disambiguation via Wikidata & Schema
If an AI model cannot distinguish your company from an unrelated entity with a similar name, it will simply omit your brand from recommendations. Establish clear entity boundaries:
- Create and maintain a verified Wikidata item detailing founding dates, corporate leadership, and headquarters coordinates.
- Deploy comprehensive
Organizationschema featuring an exhaustivesameAsarray linking your official profiles on LinkedIn, Crunchbase, Wikipedia, and Bloomberg. - Maintain an active Google Knowledge Panel by verifying your brand identity through Google Search Console.
2. Optimize for Co-Occurrence in Tier-One Editorial Media
In the generative era, unlinked brand mentions in prestigious media outlets carry immense algorithmic weight. When publications like The Wall Street Journal, TechCrunch, or Forbes mention your company alongside terms like “market leader in enterprise cybersecurity”, language models update their internal vector weights during continuous pre-training and fine-tuning.
3. Anchor Executive Profiles into the Professional Knowledge Graph
An enterprise entity is inextricably linked to the human experts behind it. To satisfy AI quality evaluators:
- Transform founder and C-suite bios into verified
Personschemas connected to the parent organization. - Link executive credentials to patents, academic research on Google Scholar, and verified conference keynotes.
- Publish original executive thought leadership on corporate platforms rather than solely relying on third-party channels.
4. Monitor and Protect Your AI Brand Sentiment
Conduct regular algorithmic audits by testing standard commercial prompts across ChatGPT, Perplexity, and Gemini. If AI models synthesize outdated pricing, misattribute features to competitors, or produce hallucinations regarding your services, execute targeted digital PR and structured documentation updates to correct the web-wide consensus.
Protect and Scale Your Brand’s Authority in AI Search
At SEO Sadhu, we help enterprise organizations build dominant brand entities that AI models trust, recommend, and cite. Let us secure your company’s rightful position at the forefront of the generative search revolution.
Frequently Asked Questions (FAQ)
Can an agency guarantee that our brand will be recommended by ChatGPT?
No ethical agency can guarantee specific AI outputs because LLM responses are generated probabilistically based on complex neural networks. However, by establishing verified entity consensus, publishing original research, and earning high-authority media mentions, you can dramatically elevate the mathematical probability of your brand being recommended.
How does an entity-based SEO approach differ from keyword-based SEO?
Keyword-based SEO focuses on optimizing web pages for specific literal text strings. Entity-based SEO focuses on establishing distinct digital identities (concepts, people, organizations, products) and defining their relationships in machine-readable knowledge graphs that search engines and AI models understand conceptually.
What is the most common reason AI assistants hallucinate facts about a business?
Hallucinations occur when an AI model encounters conflicting, ambiguous, or sparse information across the web. Publishing clear, authoritative documentation, updating structured schema, and maintaining consistent data across public registries provides the ground truth models need to generate accurate responses.